JPG
When I do my expenses, I usually have a bunch of .jpg files. I wanted to be able to scan the .jpg but wanted to search for particular content (e.g. $89.33)
I created a python script that uses tesseract to OCR the .jpg and search.
Tesseract is the core optical character recognition (OCR) engine, while Pytesseract is a Python wrapper that provides an interface to run the Tesseract engine from within Python code. You cannot use Pytesseract without having the Tesseract engine installed separately on your system. Below is based on macOS running Homebrew.
UPDATE: You can now search .jpg, .png, and HEIC format. Also, the script is self contained and will install everything it needs. The new script will creates a hidden .venv folder with everything it needs. So it is self contained now.
The script will ask you what directory you want to search.. by default it will be the pwd
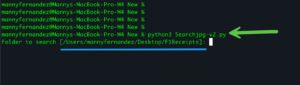
Next, it will read all the files.
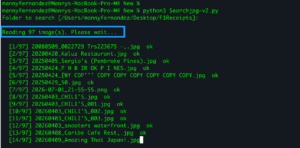
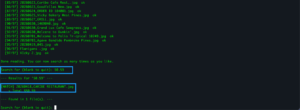
Once it is done reading the files, you can ask for something to search. The prompt stays open and will take new searches until you close the script.
Installing Requirements
See Update Above
brew install tesseract
python3 -m pip install pytesseract pillow
Running the Script
The script will require a couple of things; 1st is the text you are searching for and the 2nd is the location of the files.
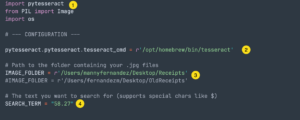
- Here it imports the
pytesseract - The location of your
tesseract - The location of the files. Since I have multiple computers, the path are a little different.
- What we are looking for.
When the script is run, it will scan the files are return the name of the files where it found the keyword we are searching for.
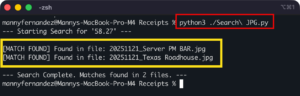
The way I run it is that I have the script open in Sublime Text. I had two folders so I would keep the script open, make mods to path (which folder to search) and what to actually search.
PDFs
For PDFs, I use pdfgrep which is an Open Source project. The use case is that after I am done filling out a report, I can save it as a PDF. Sometimes, I find a receipt and want to make sure if I already expensed it or not. Rather than openinging every PDF and searching it, I use pdfgrep. To install on macOS (If you are running Homebrew)
brew install pdfgrep
To run pdfgrep you can either run it against a file or an entire directory. In my workflow, I want to scan all the PDF’d reports to ensure I expensed a particular charge based on the amount. In this example, I am searching for 51.96 which is the amount I want to check.
pdfgrep -ril "51.96" /Users/mannyfernadez/Desktop/Reports > matches.txt
-r –recursive
Recursively search all files (restricted by –include and –exclude) under each directory, following symlinks only if they are on the command line.
-i –ignore-case
Ignore case distinctions in both the PATTERN and the input files.
-l –files-with-matches
Suppress normal output. Instead print the name of each input file that contains a match. This works well with -Z, but many other output options like -n or -c are ignored when -l is specified.
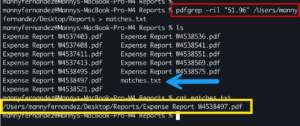
This allows me to validate the expense by going directly to the file.